What wrong docs cost test automation teams
A stale Cypress example does not just break one test. It breaks 200 tests across 50 teams on Monday morning. Here is the real cost.
- Written by
- Lucas Suárez (opens in a new tab)
- Published on
- Read time
- 6 min
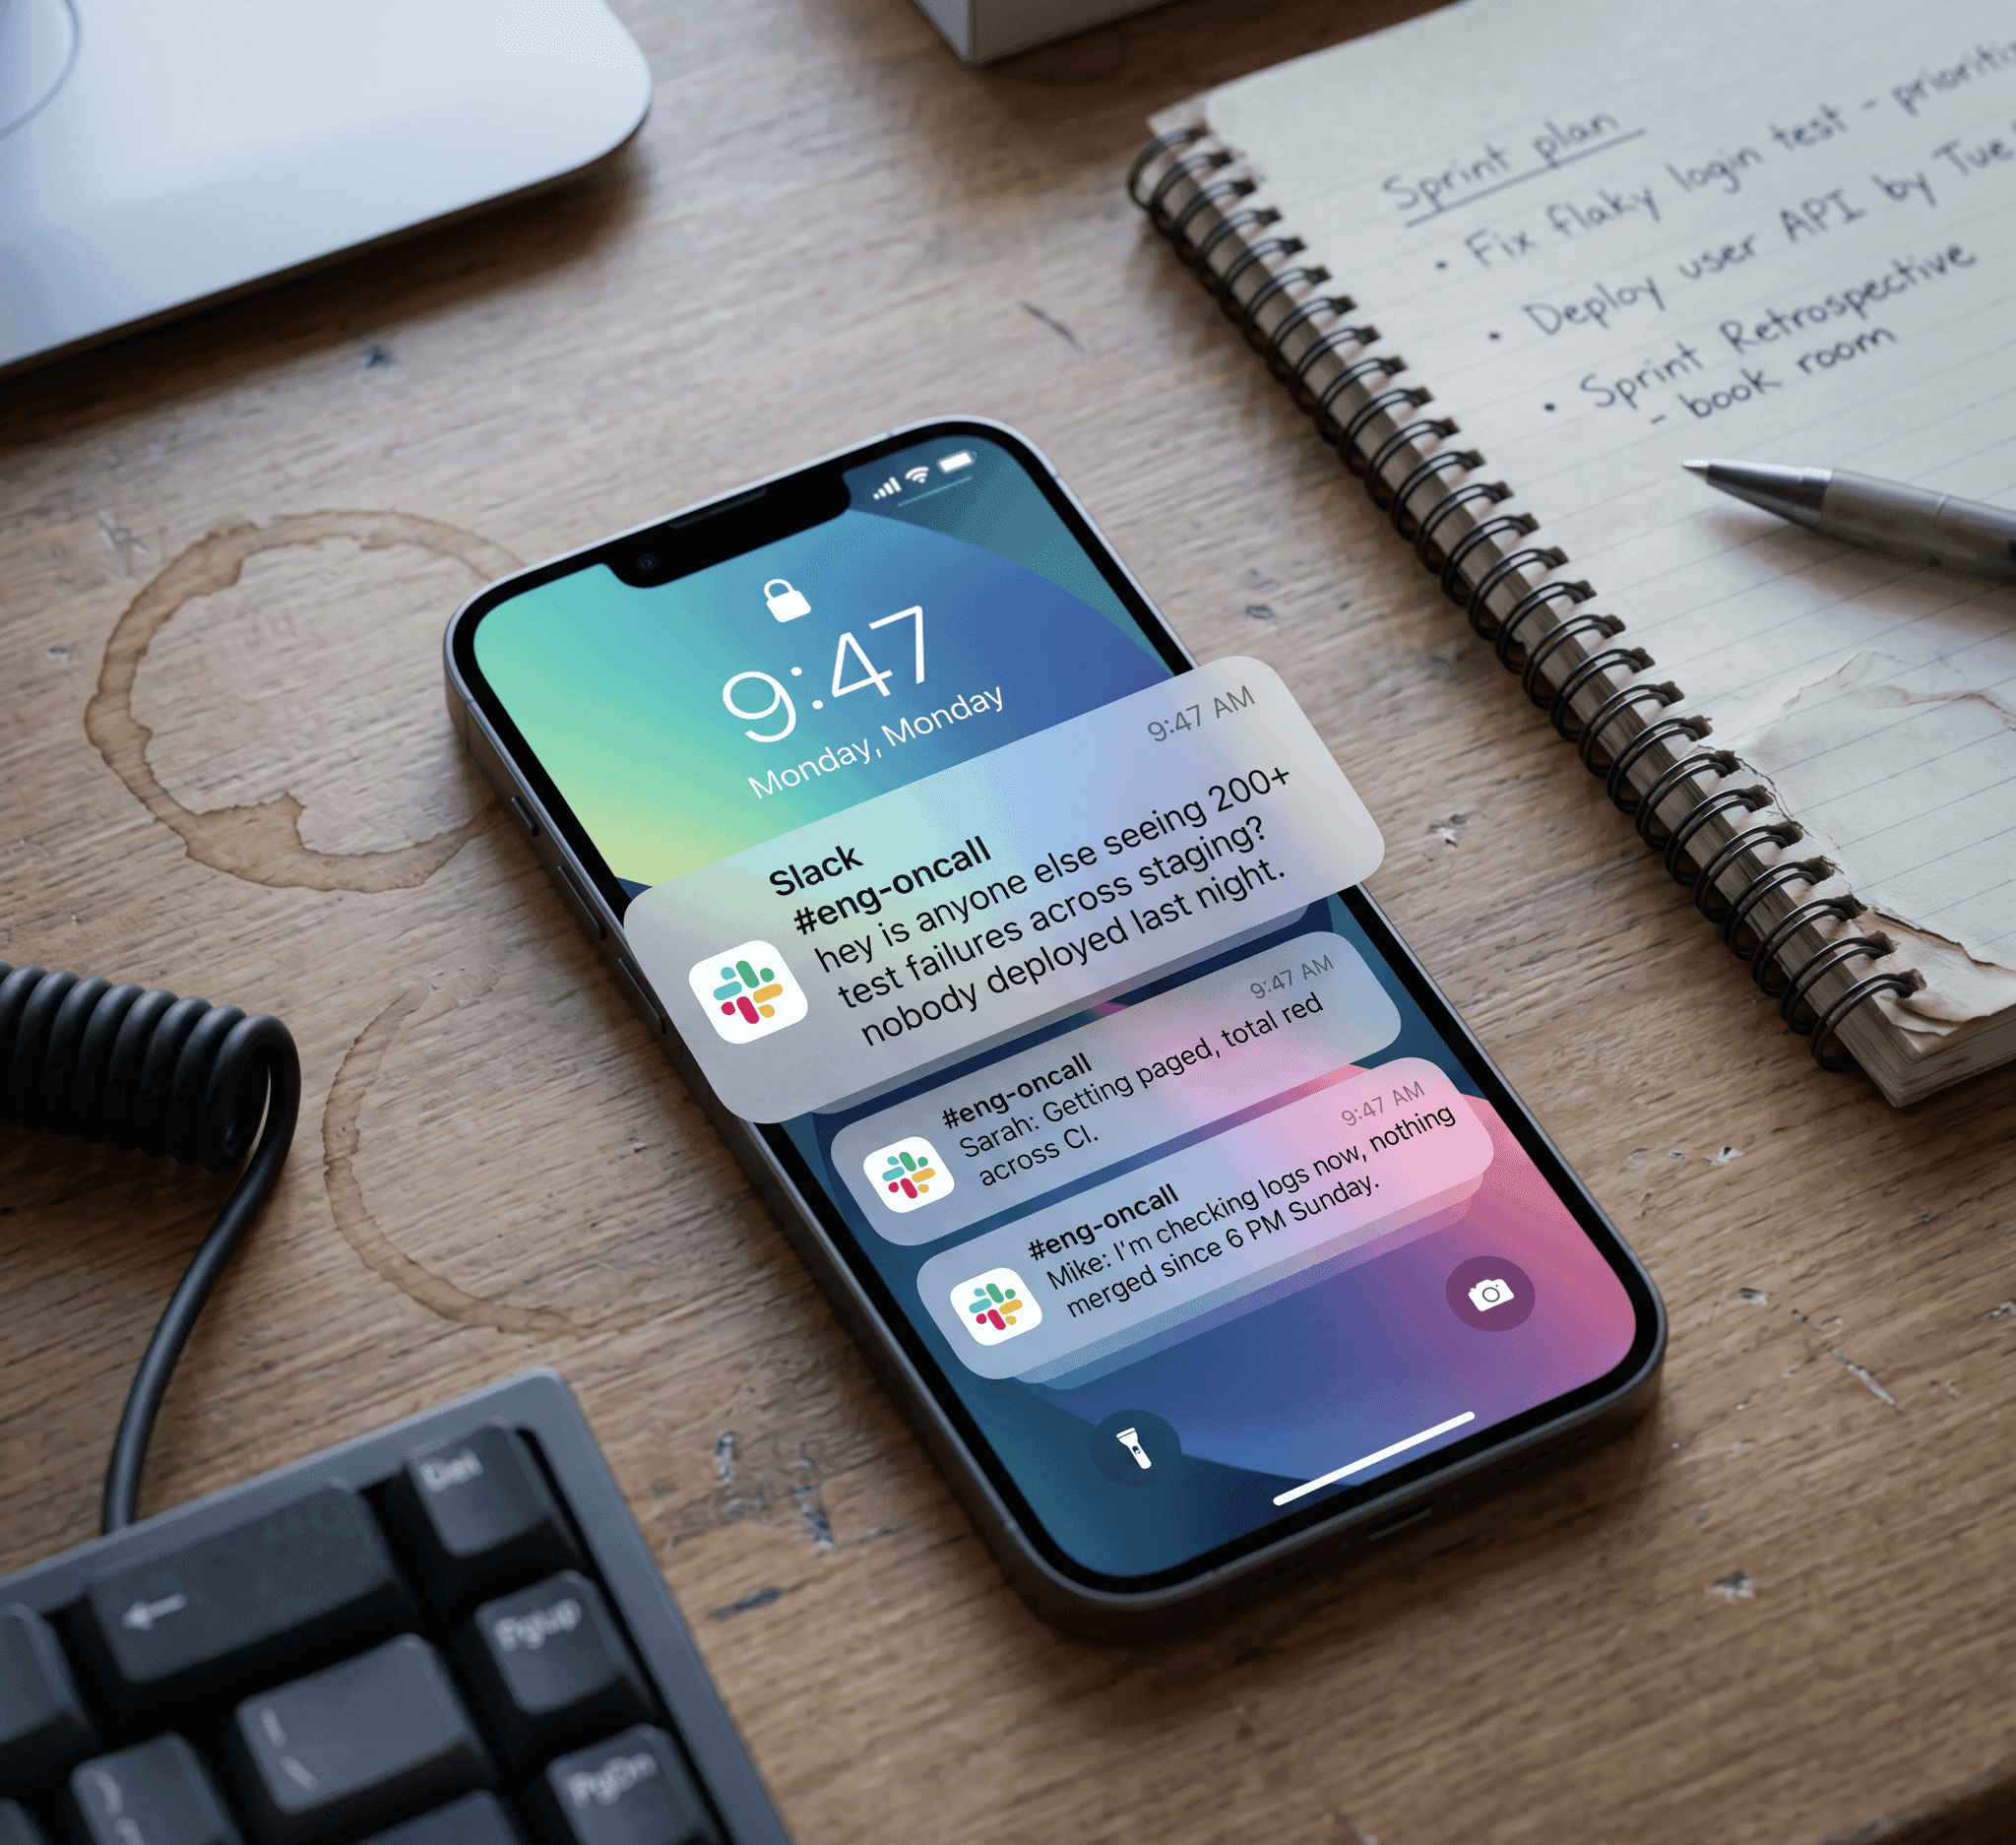
A QA engineer copies a Cypress test example from your documentation. It passes locally. It passes in CI. It ships to production monitoring. Three months later, Cypress releases a major version, the example uses a deprecated command, and 200 tests across 50 teams start failing on Monday morning.
Nobody changed the tests. Nobody changed the application. The documentation was wrong, and the tests were built on it.
In test automation, a wrong code example does not break one test. It breaks every test that was modeled after it.
The ecosystem is massive
Test automation frameworks are not niche tools anymore. Playwright has 85,100 GitHub stars and 451,000+ dependent projects. Cypress has 49,600 stars and 1.5 million projects using it. These are not libraries that a handful of teams depend on. They are infrastructure.
Playwright publishes documentation across four languages: Node.js, Python, Java, and .NET. Each language needs its own API examples, configuration guides, and integration tutorials. That is four times the surface area for documentation drift.
Cypress has shipped 389 releases since its inception. Each release can deprecate commands, change default behaviors, or introduce new APIs. A code example written for Cypress 12 may use cy.intercept() patterns that behave differently in Cypress 15. The example still runs. It just does not do what the developer expects.
When a testing framework has hundreds of thousands of dependents, every stale example multiplies. A wrong page.locator() example in Playwright's docs does not affect one team. It affects every developer who reads it and patterns their test suite after it.
The math
Here is what stale documentation costs when it reaches test automation teams at scale.
Test maintenance: 40-60% of all testing effort
The Capgemini World Quality Report consistently finds that test maintenance consumes 40-60% of total testing effort. That is not writing new tests. That is fixing existing ones that broke because something changed.
Stale documentation makes this worse. When a QA engineer fixes a failing test, the first thing they check is the framework's documentation. If the docs still show the old pattern, the engineer does not know whether the test is wrong or the framework changed. They spend time debugging a problem that accurate documentation would have prevented.
The Katalon State of Software Quality Report 2025 found that only 11% of QA teams have reached an optimized level of test automation maturity. The other 89% are still struggling with maintenance, flaky tests, and tooling challenges. 56% of QA teams report they cannot keep up with testing demands. Documentation that adds friction instead of removing it makes this gap wider.
Developer churn: 72% abandon over bad docs
The Postman 2023 State of the API Report found that 72% of developers have abandoned an API due to poor documentation. 54% cite documentation as the number one factor when evaluating a tool.
In the test automation market, this matters more than in most categories. Major end-to-end frameworks like Cypress, Playwright, and Selenium, plus a growing layer of AI-assisted testing tools, all compete for the same teams. Switching costs are lower than in most enterprise software because test frameworks are typically adopted bottom-up by individual engineers, not purchased top-down by procurement.
A developer evaluating Cypress versus Playwright will follow the quickstart guide. If the first code example does not work, they do not file a bug report. They try the other framework. The Stack Overflow Developer Survey 2023 found that 90.36% of developers use technical documentation as their primary learning resource. Your docs are the product evaluation.
CI/CD pipeline failures: the silent cost
When a test example in documentation uses a deprecated assertion or an outdated selector strategy, the developer does not discover it immediately. The test passes locally with a cached dependency. It passes in CI with a pinned version. The problem surfaces when the team upgrades the framework version, or when a new team member follows the same docs and gets a fresh install.
Each engineering-escalated support ticket costs $150 to $250 (industry estimate, DevRelCon / MetricNet). For a testing framework with thousands of users, a single stale example that generates 100 support tickets costs $15,000 to $25,000 in direct support. But the real cost is the engineering hours spent debugging a documentation problem instead of shipping features.
Compliance: the cost nobody budgets for
Test documentation is not optional in regulated industries.
SOC 2 Type II audits require documented testing processes, test plans, and evidence of test execution. If your documentation instructs teams to set up testing in a way that does not align with your current API, the test evidence they produce may not satisfy auditors.
ISO 27001 requires documented security testing procedures. FDA 21 CFR Part 11 requires validated test documentation with audit trails for medical device software. PCI-DSS v4.0 requires documented penetration testing methodology.
In each case, the documentation that developers follow to configure and run tests becomes part of the compliance evidence chain. Wrong documentation does not just break tests. It creates compliance gaps.
What this looks like in practice
Your testing framework docs show a page object pattern:
// Illustrative: Cypress 12 page object pattern
class LoginPage {
 visit() {
   cy.visit('/login')
 }

 fillUsername(username) {
   cy.get('#username').type(username)
 }

 fillPassword(password) {
   cy.get('#password').type(password)
 }

 submit() {
   cy.get('form').submit()
 }
}
But Cypress 15 recommends the App Actions pattern and cy.session() for authentication:
// Illustrative: Cypress 15 recommended pattern
Cypress.Commands.add('login', (username, password) => {
 cy.session([username, password], () => {
   cy.visit('/login')
   cy.get('[data-testid="username"]').type(username)
   cy.get('[data-testid="password"]').type(password)
   cy.get('[data-testid="submit"]').click()
   cy.url().should('include', '/dashboard')
 })
})
Both compile. Both run. But the first pattern creates a new browser session for every test, making the suite 3-5x slower. A team that follows the old documentation builds 500 tests on the slow pattern before discovering the performance issue. Rewriting 500 tests is not a bug fix. It is a quarter of engineering time.
The fix
Test automation documentation has a unique challenge: frameworks release fast, and every release can change how examples should be written.
Three things close the gap:
1. Automated review on every PR. When framework code changes, check if documentation references the changed commands, selectors, or configuration options. Flag stale examples before they merge. For a framework shipping 30+ releases per year, manual review cannot keep pace. A CI step that scans docs for references to modified APIs catches drift at the source.
2. Version-aware example validation. Your documentation linting should know which framework version each example targets. An example using cy.server() (removed in Cypress 12) or page.waitForNavigation() (deprecated in Playwright) should trigger a warning. Not after a user reports it, but in the PR where the deprecation happens.
3. Cross-language freshness tracking. For frameworks like Playwright that publish docs in four languages, track which language variants have been updated when the underlying API changes. A Node.js example that gets updated while the Python equivalent does not creates an inconsistency that users of the less-maintained language will hit.
If your testing framework documentation is the first thing a QA engineer reads when evaluating your tool, it needs the same quality bar as the framework itself.
EkLine automates documentation review in your GitHub PR workflow, catching stale code examples, broken links, and style violations before they reach developers. See how it works.